AI document classification for accountants: practical guide
By The AI Ledger editorial team | Published 2026-07-30 | Updated 2026-11-20
AI document classification for accounting automatically identifies and tags financial documents so your practice can route, extract, and post entries with less manual work. The classifier reads each incoming file, assigns a document type (invoice, bank statement, purchase order), attaches a confidence score, and hands it to the right downstream process. Done well, that means less manual sorting and a traceable record of how each document was handled.
In this guide:
- How AI document classification works and how it differs from full Intelligent Document Processing
- The document types and accounting use cases where it delivers the clearest payback
- A vendor evaluation checklist and the questions to ask on demos
- A step-by-step pilot plan for UK practices, including integration with Xero, Sage, QuickBooks, and FreeAgent
- * *
Table of Contents
- What is AI document classification in accounting?
- How does the classification pipeline actually work?
- Which classification approach suits your document types?
- Where does classification deliver the biggest payback in accounting?
- How do you implement AI document classification in your practice?
- What should UK accountants look for when choosing a solution?
- How do you measure success and maintain governance?
- Where can you find and evaluate tools?
- Key takeaways
- Find the right classification tool
- Useful sources
What is AI document classification in accounting?
AI document classification is the process of automatically assigning a type label and a confidence score to an incoming financial document. Feed the system a PDF and it returns something like: _Invoice, 0.97_. That label then acts as the gate for everything that follows: which data extractor runs, which approval workflow fires, which ledger account gets updated.
It is worth being precise about where classification ends and Intelligent Document Processing (IDP) begins. Classification is one stage inside a broader IDP pipeline. IDP covers the full journey: ingest, classify, extract field values, validate against rules, and post to your ERP or accounting software. You can deploy a classifier as a standalone improvement to your document intake without committing to a full IDP project, and for many smaller practices that is the right starting point.
For accounting specifically, classification also enriches files with structured metadata such as date, amount, supplier, and document number. That metadata makes records traceable, which helps when HMRC or an external auditor asks you to reconstruct a transaction trail.
Key distinctions to keep in mind:
- Classification identifies document type and confidence; it does not extract line items or post entries.
- IDP is end-to-end: classify, extract, validate, route, post.
- Precision and recall are the standard accuracy metrics; confidence thresholds control when a document goes to human review rather than straight-through processing.
- Classification metadata supports your audit trail from the moment a document arrives.
If your main problem is documents landing in the wrong inbox or triggering the wrong extractor, a standalone classifier may be enough without a full IDP deployment.
- * *
How does the classification pipeline actually work?
LlamaIndex's practical classification guide describes six stages that map onto an accounting intake workflow.
- Ingestion and OCR. Documents arrive by email, upload portal, or API. Optical character recognition converts scanned images and PDFs into machine-readable text. Quality here sets the ceiling for everything downstream.
- Pre-processing. The system cleans the text: removes headers and footers, normalises whitespace, corrects common OCR errors, and parses layout zones (header block, line-item table, footer totals).
- Feature extraction. The model pulls text features (keywords, amounts, VAT numbers), layout features (position of date fields, table structures), and visual cues (logos, stamps, signature blocks). Multimodal models analyse visual layout and text together, which suits semi-structured finance documents like invoices and remittance advices.
- Model inference and class assignment. The model scores the document against each class in its taxonomy (invoice, credit note, bank statement, purchase order, expense receipt, contract, and so on) and assigns the highest-scoring label.
- Confidence scoring and routing. Every classification comes with a confidence score. If the score exceeds the class threshold, the document routes automatically to the correct extractor or workflow. If it falls below the threshold, it moves to a human review queue, which keeps misroutes out of your ledger.
- Tagging and downstream handoff. Confirmed documents are tagged with metadata and passed to the next stage: a field extractor, an approval workflow, or direct API posting to Xero, Sage, or QuickBooks.
Model approaches at a glance:
| Approach | How it works | Best fit for accounting |
|---|---|---|
| Supervised (custom) | Trained on labelled examples from your own document set | High-volume, consistent document types where you have plenty of labelled examples per class |
| Pre-trained (fine-tuned) | General model fine-tuned on finance documents | Good starting point; faster to deploy than building from scratch |
| Zero-shot | Classifies without task-specific training data | Useful for rare document types or early pilots with limited labelled data |
| Rules/hybrid | Keyword and layout rules combined with ML scoring | Reliable for highly structured documents like standard bank statements |
!Accountant working with AI document software
Set confidence thresholds per class rather than one cut-off for everything. A misrouted invoice that auto-posts costs more than a contract sent for review, so invoices usually warrant a stricter threshold.
- * *
Which classification approach suits your document types?
Not all financial documents are the same shape, and the classification technique you choose should reflect that. There are three broad approaches to how a model reads a document.
!Infographic showing classification approaches comparison
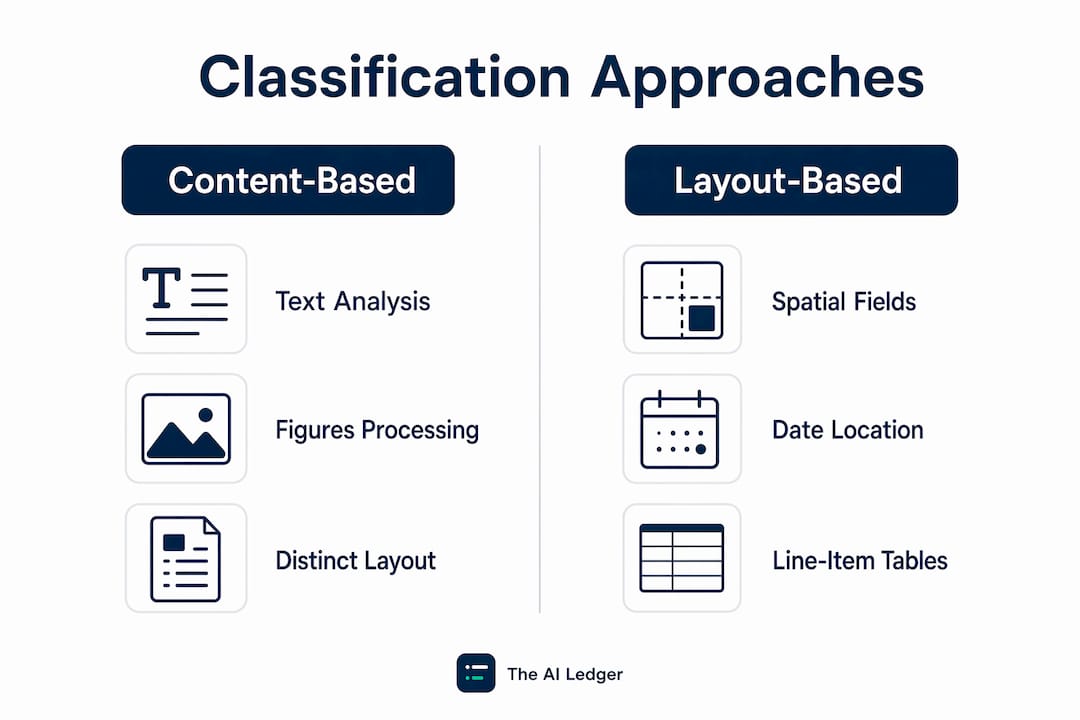
Content-based classification looks at the words and figures in the text. It works well for documents with distinctive language, such as contracts or board minutes, where the vocabulary itself signals the type.
Layout-based classification uses the spatial arrangement of fields: where the date sits, whether there is a line-item table, where the total appears. Invoices and purchase orders are natural fits here because their structure is more diagnostic than their wording.
!Hands sorting accounting documents on table
Multimodal classification combines both. It suits finance documents because they are semi-structured: they share layout conventions but vary in wording across suppliers and clients.
Single-label vs multi-label classification is a practical decision. Single-label assigns one type per document, which is sufficient for most routing tasks. Multi-label is needed when a document legitimately belongs to more than one category. A supplier document that is simultaneously a credit note and an expense claim is a real example; forcing it into one bucket causes downstream errors.
- Supervised custom models need a good stock of labelled training data for each class. V7 Labs provides annotation and training tooling that teams use to build and label these datasets for custom classifiers.
- Pre-trained models from vendors like ABBYY, which offers purpose-built classification and splitting for high-volume document sorting, reduce the labelling work.
- Zero-shot models are useful for rare document types or when you are piloting before committing to a labelling project.
- Rules/hybrid approaches remain competitive for highly standardised documents and are often the most auditable option for regulated environments.
Our guide to machine learning accounting basics) covers the model trade-offs in plain English.
- * *
Where does classification deliver the biggest payback in accounting?
The highest-return use cases share a common trait: high document volume, repetitive routing decisions, and a clear downstream action that classification can trigger automatically.
- Accounts payable (invoices and credit notes). Classifying invoices with AI is the most common entry point. The classifier identifies the document type, routes it to the field extractor, and triggers a three-way match against the purchase order and goods receipt before posting, so staff deal with exceptions rather than sorting every document.
- Expense processing. Receipts arrive as photos, PDFs and forwarded emails. A classifier normalises the intake, separates receipts from invoices, and routes each to the correct expense category extractor.
- Bank statement routing. Statements from multiple banks and in multiple formats need to reach the right reconciliation workflow. Classification handles the sorting, which helps practices managing many client entities. See also our guide to bank reconciliation software.
- Purchase orders and three-way matching. Classifying POs separately from invoices is the prerequisite for automated matching. Without it, the matching logic has no reliable way to know which document is which.
- Contract triage for lease accounting. AI can classify incoming contracts and route lease agreements to a specialist extractor that pulls clause data for IFRS 16 schedules. Nominal describes IDP generating lease schedules directly from extracted clause data. Our lease accounting automation guide covers this in more depth.
- Client document onboarding for bookkeeping. When a new client sends a bundle of historical records, a classifier sorts them by type before anyone opens them.
For how classification fits into the month-end cycle, see our guide to AI tools for the financial close process).
- * *
How do you implement AI document classification in your practice?
Classification projects usually stall on poor document intake rather than on the model. Standardising incoming formats before you deploy reduces false positives and the review workload.
Pilot checklist
- Define the scope. Pick two or three document types with the highest volume: typically invoices, receipts, and bank statements. Set your own target touchless rate (the share of documents processed straight through) and a maximum acceptable misclassification rate.
- Standardise intake. Request digital PDFs from suppliers and clients rather than photos or scanned images. Enforce a consistent naming convention for uploaded files. This can improve accuracy before any model work begins.
- Gather and label training data. Collect a good number of examples per class from your real document history; ask the vendor how many their model needs. Use a labelling tool (V7 Labs is one option for teams building custom classifiers) to annotate document types consistently.
- Train or configure the model. For a small practice, a pre-trained vendor model fine-tuned on your document set is usually faster and cheaper than building from scratch. For a mid-sized firm with unusual document types, a custom supervised model may be worth the investment.
- Set confidence thresholds per class. Route documents below the threshold to a human review queue rather than auto-posting.
- Run a parallel pilot. Process a sample of real documents through the classifier alongside your existing manual process. Compare outputs, measure precision and recall, and identify the classes with the highest error rates.
- Build the feedback loop. Human corrections in the review queue should feed back into the model as new labelled examples. This is the mechanism that prevents model drift over time.
- Integrate with your accounting software. Map classifier metadata fields to your chart of accounts and connect via API or middleware.
Integration options for UK accounting stacks
- Xero and QuickBooks: Both offer open APIs. Most IDP vendors provide direct connectors or publish integration guides. Middleware platforms can bridge gaps where native connectors do not exist.
- Sage: Sage's API ecosystem supports custom integrations; some IDP vendors offer pre-built Sage connectors.
- FreeAgent: API access is available for developers; check vendor documentation for pre-built support.
- ERP systems: For mid-sized firms on Microsoft Dynamics or SAP, SAP Document AI offers enterprise classification with explicit data governance controls, including a policy that no customer data is used for model retraining without consent.
Our accounting workflow automation examples show how classification connects to downstream posting.
Timeline and effort
A small practice with two or three document types needs far less time than a larger firm with many document types and an ERP integration. Budget mainly for labelling time, vendor setup and, for larger firms, integration testing and staff training. Ask each vendor for a realistic pilot timeline based on your document volumes.
Treat the classifier as an integration project from day one: map metadata fields to your accounting software's API objects before configuring anything.
- * *
What should UK accountants look for when choosing a solution?
The evaluation criteria below apply whether you are assessing a standalone classifier or a full IDP platform with classification built in.
| Evaluation dimension | What to look for |
|---|---|
| Primary use case and document types | Does the vendor have pre-trained models for invoices, receipts, bank statements, and contracts? |
| Model approach | Pre-trained, custom supervised, zero-shot, or hybrid? Can you add custom classes? |
| Integration options | Native connectors for Xero, Sage, QuickBooks, FreeAgent, or your ERP? REST API available? |
| Deployment and data residency | Cloud, on-premises, or hybrid? Where is data stored? Is UK or EU data residency available? |
| Accuracy and monitoring | Can you see per-class precision and recall? Are confidence scores exportable? |
| Human-in-the-loop support | Is there a built-in review queue? Can corrections feed back into retraining? |
| Pricing and timeline to production | Is pricing per document, per user, or flat fee? What is the realistic time to a working pilot? |
Questions to ask on vendor demos:
- What is your average precision and recall on invoices and receipts out of the box?
- Can I export confidence scores and classification decisions for audit purposes?
- Where is my data stored, and is UK or EU data residency available?
- What is your retraining policy? Can I trigger retraining from human corrections?
- Do you have native connectors for Xero, Sage, or QuickBooks?
- What does your human review queue look like, and how do corrections feed back into the model?
Red flags to watch for:
- No audit trail or no ability to export classification decisions with timestamps
- Confidence scores not visible or not exportable
- Vague or absent GDPR and data residency statements
- No retraining mechanism or opaque retraining policy
- Integration limited to file export rather than API posting
For smaller practices, ease of use and a fast time to value usually outweigh deep customisability. For mid-sized firms with complex document types or ERP requirements, the ability to train custom classes and integrate via API becomes the deciding factor.
- * *
How do you measure success and maintain governance?
Good governance starts with the right metrics. Track these per class, not just as an aggregate.
| Metric | What it measures | Target guidance |
|---|---|---|
| Precision (per class) | Of documents classified as type X, how many actually are X? | Set per class by cost of error |
| Recall (per class) | Of all actual type X documents, how many did the model catch? | Set per class by cost of error |
| F1 score (per class) | Harmonic mean of precision and recall | Use to compare classes fairly |
| Touchless rate | % of documents processed without human intervention | Track as your primary business KPI |
| Exception rate | % of documents routed to human review | Should fall over time as the model improves |
| Cycle time | Average time from document receipt to ledger posting | Baseline before go-live; track weekly |
Confidence thresholds are the primary governance lever. Set them per class based on the cost of a misclassification: a wrongly routed invoice that auto-posts is more damaging than a contract that goes to the review queue. Review thresholds quarterly and adjust based on observed exception rates.
Keep a full audit trail. Every classification decision should be logged with a timestamp, the assigned class, the confidence score, and the identity of any human reviewer who overrode the model. This log is what you hand to an auditor. Our guide on why AI reduces accounting errors) covers how structured metadata capture supports traceability in practice.
GDPR and data residency: Under UK GDPR, financial documents containing personal data (supplier names, employee expense receipts) must be processed lawfully and stored securely. Confirm that your vendor offers UK or EU data residency, has a clear data processing agreement, and does not use your documents to train shared models without explicit consent. SAP Document AI, for example, states explicitly that no customer data is used for retraining without approval, which is the standard you should hold all vendors to.
Run a monthly sampling check: pull a random sample of classified documents, verify the labels by hand and log the results. That gives auditors evidence and warns you of model drift early.
- * *
Where can you find and evaluate tools?
The AI Ledger directory lists 300+ tools for accountants and bookkeepers, each with an editor score and a last verified date; scores are never for sale. The data entry and receipts category covers capture and classification tools such as Dext, AutoEntry, Datamolino, Veryfi and Nanonets. The finder matches tools to your task, software and practice size, and compare puts them side by side.
Outside the directory, these names come up for classification and IDP:
- ABBYY: A long-established IDP vendor with purpose-built classification and splitting capabilities, high-volume document sorting, and metadata enrichment, mainly used by larger organisations.
- LlamaIndex: A developer-focused framework that covers the full classification pipeline from ingestion to routing. Useful for teams building custom solutions or integrating classification into existing Python-based workflows.
- V7 Labs: Annotation and training tooling for teams building custom classifiers on their own document datasets. Particularly relevant if you need to label a proprietary training set before fine-tuning a model.
For technical depth, the following public resources are worth bookmarking:
- Nanonets' guide to document classification covers multimodal model approaches in accessible detail.
- Nominal's blog on AI document processing explains how classification connects to ERP-native record creation.
- DocuWare's IDP explainer sets out the classification-versus-IDP distinction clearly.
When reviewing vendor pages, look for precision and recall figures on accounting document types specifically. Overall accuracy alone does not show where a model struggles.
- * *
Key takeaways
AI document classification sorts incoming documents so the right extractor and workflow handle each one, and the log it keeps supports your audit trail.
| Point | Details |
|---|---|
| Start with a focused pilot | Pick two or three high-volume document types and set a clear touchless rate target before you go live. |
| Standardise intake first | Requesting digital PDFs and enforcing naming conventions improves classifier accuracy before any model work begins. |
| Require an audit trail | Log every classification decision with a timestamp, confidence score, and reviewer identity. |
| Measure touchless rate | Track the percentage of documents processed without human intervention as your main business measure. |
| Use corrections as training data | Feed reviewer corrections back into the model so the exception rate falls over time. |
| Use The AI Ledger to shortlist | The directory of 300+ tools and the finder help you build a shortlist. |
- * *
Find the right classification tool

Start with the data entry and receipts category, use the finder to match tools to your software and practice size, and line up two or three with compare. Every listing has an editor score and a last verified date. The free newsletter covers new tools, feature updates and price changes, and our guide on why accountants adopt AI tools) looks at the adoption patterns that last.
- * *
Useful sources
- DocuWare: What Is Intelligent Document Classification?, best for defining classification vs IDP and sourcing confidence threshold guidance
- Dina-ia: Classification of accounting documents, metadata enrichment and auditability use cases
- Nominal: AI Document Processing, practical implementation guidance and ERP integration examples
- Nanonets: A guide to document classification, technical explainer on multimodal models and OCR
- SAP Document AI, enterprise data governance and deployment model reference
- LlamaIndex: AI Document Classification, developer-focused pipeline stages reference
- ABBYY: AI Document Classification and Splitting, established IDP vendor capability reference
> "Practitioners should distinguish classification from IDP: classification identifies the document and confidence, IDP executes extraction, validation and posting." Source: DocuWare IDP explainer.
_This article is general information for UK accounting professionals, not legal, tax, or regulatory advice. Confirm current GDPR obligations and data residency requirements with a qualified adviser or the ICO for your specific situation._
Recommended
- Accountant AI tool comparison guide for 2026)
- AI in accounting explained: the 2026 professional guide
- Machine learning accounting basics: a 2026 guide)
- Why accountants adopt AI tools: a 2026 guide)