How accurate is AI at reviewing financial statements?
By The AI Ledger editorial team | Published 2026-08-06 | Updated 2026-11-20
AI can accurately perform specific, well-defined financial statement review tasks when properly configured, validated, and supervised, but it is not yet reliable enough to replace human judgement on explanation, standard citation, or correction. In the FinVerBench study, models given the same verification prompt ranged from one run with a 0% false positive rate to nine of fourteen runs with false positive rates of 95-100%, seven of which flagged every clean statement as wrong. Rounding the figures also lowered recall. Both findings should shape how your firm reads any vendor claim about AI accuracy.
The picture is not all cautious. When you give a well-configured large language model (LLM) access to historical transaction data, it can detect misalignments between transactions and financial statements at a useful rate. QuantEval confirms that top proprietary models perform strongly on information extraction and some textual analysis, which maps directly to consistency checks, boilerplate detection, and cross-reference verification. Those are tasks worth automating now.
The caveats are just as important. Research on automating financial statement audits finds that accuracy drops sharply on multi-error cases, and models struggle to explain errors, cite accounting standards, or produce corrected statements. For UK firms, that gap has direct implications for ISA-compliant documentation and FRC expectations on audit evidence.
Where AI helps now:
- Data extraction from structured tables, footnotes, and XBRL filings
- Consistency and cross-reference checks across a single document
- Boilerplate and disclosure completeness screening
- High-volume routine checks that would otherwise take up staff time
Where human review remains essential:
- Explaining why a figure is wrong and citing the relevant standard
- Multi-table joint reasoning across periods or segments
- Correcting erroneous statements
- Any task where calibration has not been independently verified
Before relying on any AI output in a substantive procedure, run a small blind validation test on historical filings with known errors. It will tell you more about real-world accuracy than a vendor white paper.
- * *
Key takeaways
AI is accurate enough for specific, well-defined financial statement review tasks when validated and supervised, but human oversight remains essential for explanation, standard citation, and multi-table reasoning.
| Point | Details |
|---|---|
| Calibration drives accuracy | In FinVerBench, false positive rates under the same prompt ranged from 0% to 100% across models, and rounding lowered recall. |
| Extraction beats reasoning | AI performs strongly on data extraction and consistency checks but substantially lags human experts on multi-step quantitative reasoning per QuantEval. |
| Validate before you rely | Run a blind test on historical filings with injected errors before using any AI tool in a substantive procedure; vendor figures are not a substitute. |
| UK regulatory obligations apply | ISA (UK) documentation standards, FRC expectations, and UK GDPR all constrain how AI outputs can be used and what must be recorded in the audit file. |
| Shortlisting tools | The audit and fraud detection category in the directory of 300+ tools lists audit review tools with editor scores and last verified dates. |
- * *
Table of Contents
- How do modern AI systems approach financial statement review?
- What do published benchmarks say about AI accuracy in financial verification?
- Where does AI help, and where does it still fall short?
- What are the UK regulatory and professional obligations when using AI in reviews?
- How should your firm test an AI tool before relying on its outputs?
- How do you integrate AI into your review workflow safely?
- Should you rely on AI for this review task? A decision checklist
- How do you run an AI-assisted financial statement review step by step?
- What do independent experiments actually show about AI accuracy?
- What audit teams should actually prioritise right now
- Finding audit review tools
- Sources
How do modern AI systems approach financial statement review?
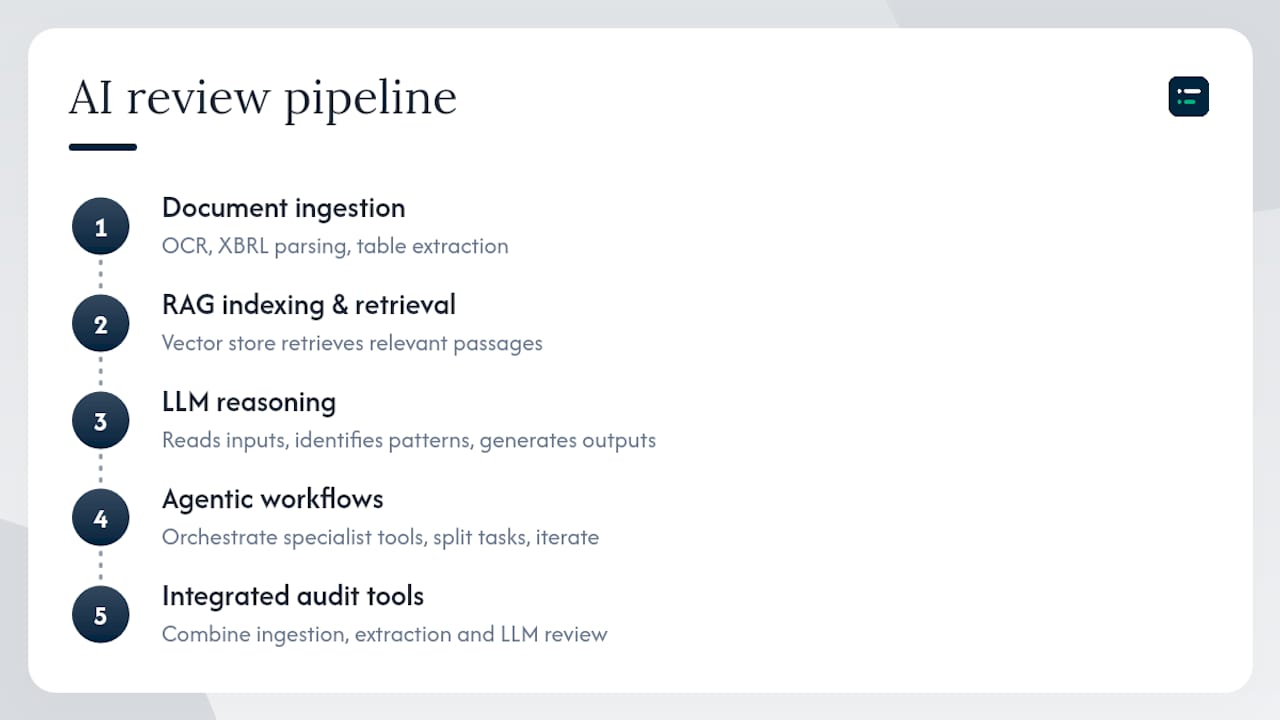
The term "AI" covers several distinct architectures, and understanding which one a vendor is using changes how you evaluate its claims. Most tools auditors encounter today combine two or three of the following patterns.
Large language models (LLMs) such as GPT-4 are the reasoning layer. They read text and structured data, identify patterns, and generate natural-language outputs. On their own, they have no access to your client's documents; they work from whatever context is placed in their input window.
Retrieval-Augmented Generation (RAG) solves the context problem. A RAG pipeline indexes source documents (annual reports, trial balances, XBRL filings) into a vector store, then retrieves the most relevant passages before passing them to the LLM for reasoning. The Amazon Bedrock deployment pattern illustrates this well: ingest financial statements, extract metrics via a foundation model, then integrate outputs into backend services. RAG grounds the model's responses in actual source documents, which reduces hallucination and supports traceability.
Agentic and workflow systems go further. Rather than a single prompt-and-response cycle, an agentic system breaks a review task into sub-tasks, calls specialist tools (an OCR parser, a calculation engine, a standards database), and iterates until it reaches a conclusion. Research on domain-specialised agentic systems recommends this architecture specifically because general-purpose LLMs fail to capture finance-specific nuances when used alone.
Structured parsers and table extractors handle the grunt work of document ingestion: OCR for scanned PDFs, XBRL parsers for tagged filings, and table extractors that convert rendered tables into machine-readable arrays. Rendering quality at this stage directly affects everything downstream. A table that arrives with merged cells or misaligned columns will produce errors that no amount of LLM reasoning can correct.
Purpose-built audit tools such as MindBridge, DataSnipper and Caseware Verity package parts of this pipeline for audit teams, rather than leaving you to work through a general chatbot.
Ask any vendor to show you the raw extracted output before the LLM reasoning step. If table structure is already degraded at that point, no downstream model will recover it.
For a broader look at how domain adaptation reduces accounting knowledge gaps, the role of AI in financial operations guide) covers pretraining considerations in practical terms.
- * *
!How do modern AI systems approach financial statement review?, overview diagram
What do published benchmarks say about AI accuracy in financial verification?
Published results vary widely, and understanding what drives that variation is more useful than quoting a single accuracy figure.
Calibration and rendering sensitivity
FinVerBench is the most direct evidence on this point. With the same prompt, most models were badly calibrated: nine of fourteen runs flagged 95-100% of clean statements as erroneous. Rounding the figures mattered too; for the best-performing model, recall fell from 100% to 79% on rounded statements while its false positive rate stayed at 0%. A vendor who reports "high accuracy" without stating the prompt, threshold and rendering conditions is giving you an incomplete number.
What the major benchmarks measure
Different benchmarks test different capabilities, and conflating them produces misleading conclusions.
- Error detection: Can the model flag that something is wrong? This is where LLMs perform best, particularly when given transaction history as context.
- Error localisation: Can the model identify which line item or cell contains the error? Performance drops here.
- Error type identification: Can the model classify the error (rounding, transposition, omission)? Weaker still.
- Explanation and standard citation: Can the model explain why the figure is wrong and cite the relevant accounting standard? Research on LLM auditing finds this is where current models consistently fall short.
QuantEval adds an important dimension: top proprietary models show strong performance on information extraction but substantially lower performance on multi-step quantitative reasoning and strategy coding compared with human experts. For financial statement review, that gap matters most in ratio analysis, segment reconciliation, and any task requiring chained calculations across multiple periods.
What a credible vendor test looks like
A vendor presenting a single precision or recall figure without context should prompt follow-up questions. A credible test will specify the dataset (real filings versus synthetic), the error injection method, the rendering format, the calibration threshold used, and the operating point selected. It will also separate detection performance from explanation performance, because they diverge significantly.
Accuracy ranges to expect from current tools:
- Routine consistency checks and extraction: generally the most reliable area for well-configured tools on structured tasks
- Single-error detection with transaction history: useful but calibration-dependent; false positive rates can be high without threshold tuning
- Multi-error cases and complex reasoning: accuracy drops; treat outputs as a first-pass flag, not a conclusion
- Explanation and standard citation: low reliability; human review is required before any output enters an audit file
When evaluating vendor accuracy claims, ask for the false positive rate at the operating threshold they recommend.
- * *
Where does AI help, and where does it still fall short?
Concrete strengths
AI tools for financial statement analysis deliver the most consistent value on tasks that are high-volume, rule-based, and well-structured.
Fast data extraction is the clearest win. Pulling figures from footnotes, XBRL tags and multi-page tables is slow by hand. A well-configured extraction pipeline handles it quickly, with traceability back to source locations.
Cross-reference and consistency checks are where AI is most useful in a review. Checking that a figure cited in the management commentary matches the primary statement, or that segment totals reconcile to group totals, is exactly the kind of pattern-matching that LLMs handle reliably.
Boilerplate and disclosure completeness screening benefits from AI's ability to compare current-year disclosures against prior-year text and against a disclosure checklist. Gaps and changes surface quickly.
Throughput on routine checks is the operational argument. Screening every line item for arithmetic consistency frees your team for the work that needs professional judgement.
Failure modes to watch for
Some limitations are structural. Research on multi-metric table generation shows that models commonly misalign columns and misplace figures across periods when generating or reasoning over multi-period tables, which reflects how LLMs handle tabular structure rather than a bug in one model version.
Operational failure modes your team should test for:
- Temporal misalignment: figures from the prior year attributed to the current year, or vice versa
- Unit and currency errors: thousands versus millions, or currency misidentification in multi-currency filings
- Omitted line items: the model summarises rather than exhaustively lists, dropping minority items
- Rounding and rendering artefacts: figures that differ by rounding convention flagged as errors, inflating false positive counts
Red flags in a vendor claim:
- Accuracy reported without specifying the false positive rate
- Tests conducted only on synthetic or simplified datasets
- No separation of detection performance from explanation performance
- No mention of calibration thresholds or operating points
As a test, inject a known rounding difference (for example, a £1 variance from a change of rounding convention) into a filing and check whether the tool flags it as a material error. If it does, expect more false positives in practice than the vendor's headline figure suggests.
- * *
What are the UK regulatory and professional obligations when using AI in reviews?
UK audit and accounting firms have specific obligations that shape how AI tools can be used in review work: what you can document, what you can rely on, and what you must disclose.
Auditing standards and FRC expectations
ISA (UK) 315 requires auditors to understand the entity and its environment, including its information systems. Using an AI tool to assess financial statements is itself part of your information-processing approach, and the tool's reliability and limitations become relevant to your risk assessment. ISA (UK) 330 requires that responses to assessed risks produce sufficient appropriate audit evidence. An AI output that cannot be traced to source documents or explained in terms of the relevant standard does not, on its own, constitute sufficient evidence.
The FRC's expectations on audit documentation mean that any AI-assisted finding that feeds into a substantive procedure needs to be documented with enough detail for an experienced auditor to understand what the tool did, what it found, and how the human reviewer assessed that finding.
UK GDPR and client confidentiality
Uploading client financial data to a cloud-based AI tool raises UK GDPR obligations. The key questions are whether the vendor processes data as a data processor under a compliant data processing agreement, where data is stored and processed geographically, and whether any client data is used to retrain or fine-tune the model. Research on AI governance for financial disclosures concludes that strong AI governance, including controls over training data and lineage, is a prerequisite for reliability. Your vendor contract should address all three points explicitly.
Audit trail and explainability
For UK firms, this means requiring tools that produce citation-linked outputs, log every query and response, and maintain version records so that a regulator reviewing your file can see exactly what the model was asked and what it returned.
Practical governance checklist
- Maintain a model register: tool name, version, vendor, last validation date
- Define human-in-the-loop rules: which outputs require human sign-off before use in a workpaper
- Document calibration settings and operating thresholds used in each engagement
- Include AI tool usage in engagement quality control procedures
- Review vendor contracts annually for data processing, model update, and liability terms
Draft a short AI tool usage policy before your first live engagement. It makes you answer the hard questions (who owns the output, what triggers escalation) before they come up mid-audit.
For practical guidance on embedding AI in internal audit workflows, the AI in internal audit guide covers control frameworks in useful detail.
- * *
How should your firm test an AI tool before relying on its outputs?
A vendor demonstration does not validate a tool. You need a reproducible test you control, on data you understand, with metrics you define. This five-stage method can be run before any tool enters a live engagement.
Stage 1: Define scope and success criteria
Decide which specific review tasks you are testing: arithmetic consistency, cross-reference checks, disclosure completeness, or error detection. Write down the precision, recall, and false positive rate thresholds your firm requires before relying on outputs. Do this before you see any results.
Stage 2: Build your test dataset
Use a mix of real historical filings (anonymised where necessary) and filings with injected errors. Inject single errors, multiple errors, rounding differences, and unit mismatches. Include at least one filing with no errors to measure false positive behaviour. Research on benchmark design confirms that datasets combining real-world tables with injected errors produce more actionable validation metrics than synthetic-only sets.
Stage 3: Establish a human benchmark
Have a qualified reviewer complete the same tasks on the same dataset without AI assistance. Record time taken, errors found, and false positives. This is your baseline. Without it, you cannot interpret the AI results.
Stage 4: Run blind tests and measure
Run the AI tool on the same dataset. Record outputs without adjusting settings between runs. Then measure against the human benchmark using the metrics below.
| Metric | What it measures | Target threshold |
|---|---|---|
| Precision | Of flagged items, what proportion are genuine errors | Define before testing |
| Recall | Of genuine errors, what proportion were flagged | Define before testing |
| Localisation accuracy | Of detected errors, what proportion were correctly located | Separate from detection |
| Explanation quality | Does the output explain the error in auditable terms | Qualitative review |
| False positive rate | Of clean items, what proportion were incorrectly flagged | Critical for workload |
| Processing time | Time to complete the defined task set | Compare to human baseline |
Stage 5: Calibrate, select an operating point, and plan monitoring
Adjust the tool's confidence threshold to find the operating point that meets your precision and recall requirements. Document that threshold. Then define a monitoring cadence: re-run the test quarterly, or after any model update from the vendor, and compare results to the baseline.
Run your test on two rendering variants of the same filing: one with rounded figures and one with full precision. In FinVerBench, rounding lowered recall, so performance on your clients' rounded accounts may be weaker than on full-precision test data.
For a broader software evaluation framework, the accounting software evaluation checklist) adapts well to AI tool procurement.
- * *
How do you integrate AI into your review workflow safely?
Procurement and testing are only the start. Safe integration requires changes to workflow, documentation, and staff responsibilities.
Procurement questions to ask vendors
- What datasets were used to train or fine-tune the model, and were they finance-domain specific?
- Does the tool produce citation-linked outputs traceable to source document locations?
- How are model updates handled, and will you be notified before a version change?
- What audit trail does the tool maintain (query logs, response logs, version records)?
- What are the SLAs for accuracy and uptime, and what remedies apply if they are not met?
- Where is client data processed and stored, and is a data processing agreement available?
Integration checklist
- Connect the tool to source documents directly (XBRL feeds, PDF ingestion) rather than manually rekeying figures
- Verify OCR and XBRL extraction accuracy before the LLM reasoning step, not after
- Assign a named human reviewer for every AI output that will enter a workpaper
- Log tool version, calibration settings, and operating threshold for each engagement
- Create workpaper templates that include a dedicated section for AI-assisted findings, the human reviewer's assessment, and the source citations
Change management and training
Staff need to understand what the tool does and what it does not do. A reviewer who treats an AI flag as a conclusion rather than a hypothesis will miss errors that the model did not catch and accept false positives without challenge. Training should cover the tool's known failure modes, the escalation route when an output looks wrong, and the firm's policy on which tasks require AI outputs to be independently verified.
Operational controls:
- Set a sampling rule: human reviewers check a defined percentage of AI-cleared items, not just flagged ones
- Define escalation thresholds: any output with confidence below a set level goes to a senior reviewer
- Document incident handling: what happens when an AI output is later found to be wrong, and how the file is updated
Build the workpaper template before your first live engagement. It records what the AI did, what the human checked and who signed off, which is what a file reviewer will look for.
For guidance on vendor selection and integration patterns, the AI tools for the financial close process guide) covers procurement considerations in depth.
- * *
Should you rely on AI for this review task? A decision checklist
Use this checklist before incorporating AI outputs into any substantive procedure.
Go criteria (all should be met before relying on AI outputs):
- The task is well-defined and bounded (e.g., arithmetic consistency check, not "review the accounts")
- The tool has been validated on a representative dataset with results documented
- The false positive rate at your chosen operating threshold is acceptable for the workload
- Citation-linked outputs are available for every finding
- A named human reviewer is assigned to assess AI outputs before they enter the file
- The vendor contract addresses UK GDPR, data processing, and model versioning
No-go criteria (any one of these should pause or block reliance):
- The tool has not been tested on data similar to the current engagement
- Accuracy claims are based on synthetic datasets only
- The tool cannot explain findings in auditable terms
- No audit trail exists for queries and responses
- The task requires multi-table joint reasoning across periods or segments without independent verification
Reliance classes and required oversight:
- Low reliance (AI as a screening tool, all outputs human-verified): suitable for most extraction and consistency tasks with validated tools
- Medium reliance (AI findings used in workpapers with selective human verification): requires documented validation, calibration records, and a sampling rule for human review of cleared items
- High reliance (AI outputs used as primary evidence in substantive procedures): requires full validation, independent corroboration of a sample, senior sign-off, and explicit documentation in the audit file
- * *
How do you run an AI-assisted financial statement review step by step?
This is the operational sequence for a single engagement, from document receipt to workpaper sign-off.
- Ingest source documents. Upload the financial statements, trial balance, and supporting schedules to the AI tool. Verify that the ingestion step has correctly parsed tables and preserved column alignment before proceeding.
- Run extraction and consistency checks. Use the AI tool to extract key figures, check arithmetic consistency, and flag cross-reference discrepancies. Record the tool version and calibration settings used.
- Review AI flags. A named human reviewer assesses each flagged item against the source document. For each flag, the reviewer records whether it is a genuine error, a false positive, or requires further investigation.
- Sample AI-cleared items. Apply your firm's sampling rule to items the tool did not flag. The sample size should reflect the tool's validated false negative rate. Document the sample selection method.
- Investigate genuine errors. For confirmed errors, the human reviewer determines the cause, the relevant accounting standard, and the required correction. The AI tool's output is supporting evidence, not the conclusion.
- Document findings in the workpaper. Each AI-assisted finding enters the workpaper with: the AI tool name and version, the calibration threshold used, the human reviewer's assessment, the source citation, and the reviewer's sign-off.
- Complete quality control review. The engagement quality reviewer checks that AI-assisted findings are documented to the firm's standard, that the sampling rule was applied, and that no AI output was used as primary evidence without human assessment.
At step 3, keep a tally of false positives. If the rate on the live engagement is clearly higher than in your validation test, pause and investigate before completing the review; the cause may be a rendering or calibration issue specific to that client's filing format.
- * *
What do independent experiments actually show about AI accuracy?
The most useful independent work on this question comes from structured benchmark studies that separate detection from explanation and test calibration explicitly, rather than reporting a single headline accuracy figure.
FinVerBench findings
FinVerBench is the most direct benchmark for financial statement verification. Its authors conclude that calibration, rather than detection, was the main problem: most models flagged nearly every clean statement as erroneous. Recall also fell when figures were rounded. A vendor who tests only on unrounded figures and reports high recall may be showing you a best-case result that does not hold on real filings.
LLM auditing experiments
The five-stage evaluation framework used in controlled LLM auditing experiments separates error detection, localisation, type identification, explanation, and correction into distinct measurement stages. Models with access to historical transaction data perform usefully on detection. Performance degrades at each subsequent stage, with explanation and correction showing the weakest results. Multi-error cases are consistently harder than single-error cases.
QuantEval and FinBen-style results
QuantEval covers a broader range of quantitative finance tasks. The pattern is consistent: strong performance on information extraction, pronounced gaps on multi-step quantitative reasoning and strategy coding versus human experts. For financial statement review specifically, this maps to a tool that reads well but calculates and reasons less reliably.
Reproducibility concerns
Prompt sensitivity is a genuine reproducibility problem. Small changes in how a question is phrased can shift outputs significantly. Benchmark validity guidance recommends range-based benchmarking rather than point-tolerance grading for valuation and qualitative tasks, because a single golden answer does not reflect the range of professionally acceptable responses.
Sample results from structured benchmarks (indicative ranges, not guarantees):
| Task | Typical AI performance | Human comparison |
|---|---|---|
| Information extraction from structured tables | Strong | Not directly compared |
| Single-error detection with transaction history | Moderate, calibration-dependent | Below experienced reviewer |
| Multi-error detection | Weaker; accuracy drops with error count | Substantially below experienced reviewer |
| Error explanation and standard citation | Weak | Well below qualified auditor |
| Multi-step quantitative reasoning | Substantially below human experts | Pronounced gap per QuantEval |
When you run your own validation test, vary the prompt phrasing across a few versions and compare results. If outputs shift with minor phrasing changes, the tool will be less reliable on new filings than its headline accuracy suggests.
- * *
What audit teams should actually prioritise right now
The useful question is which specific tasks, under which controls, AI handles reliably today.
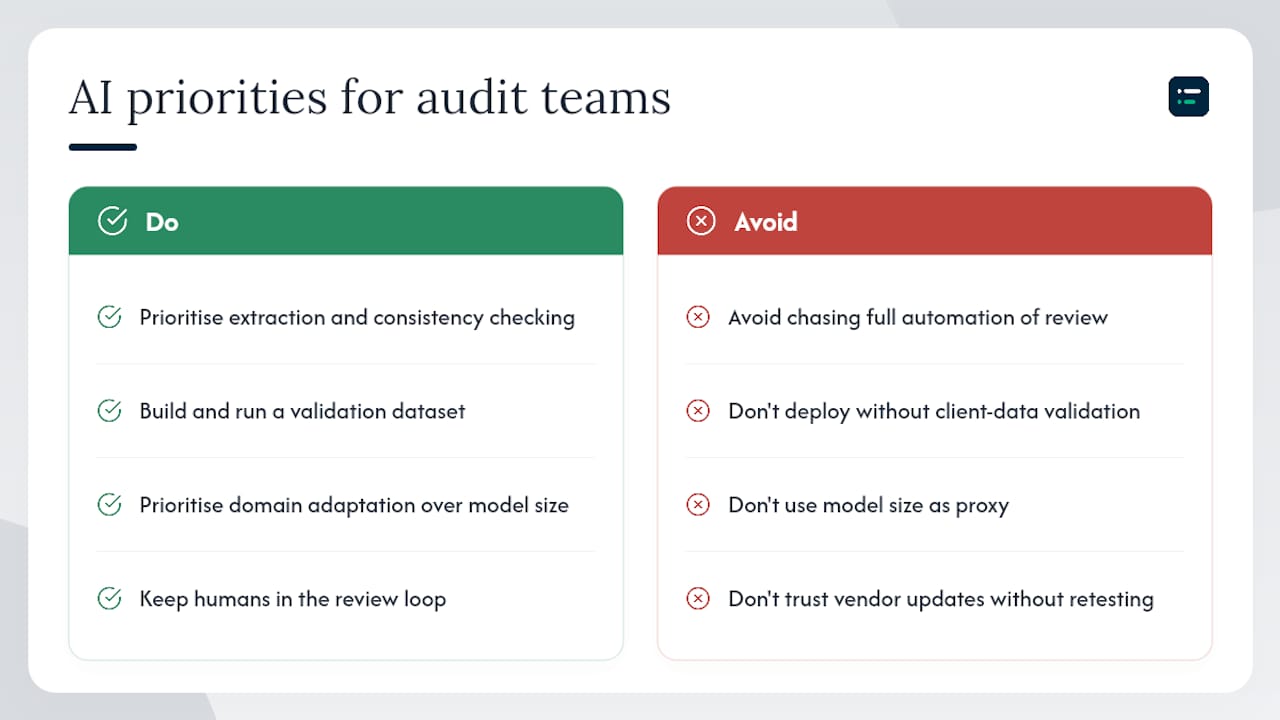
The benchmark evidence points clearly to extraction and consistency checking as the near-term wins. These are tasks where the speed advantage is real, the failure modes are detectable, and the cost of a false positive is manageable because human review catches it. Full automation of the review process is not a realistic near-term goal.
The more important investment is in validation infrastructure. Most firms do not yet have a repeatable method for testing AI tools against their own client data. Without that, every AI-assisted engagement carries undocumented risk. Building a validation dataset, even a small one, and running it against candidate tools before deployment is the most useful step a firm can take now.
Domain grounding matters as well as model size. Ask how a system is grounded in UK financial reporting material (retrieval over source documents, fine-tuning, a standards database) rather than judging it on the underlying model alone.
Keep monitoring once a tool is live. Model updates from vendors can shift calibration and performance without warning. Re-run your validation dataset at a set interval and after every vendor model update, and compare the results with your baseline.
- * *
!What audit teams should actually prioritise right now, overview diagram
Finding audit review tools
The AI Ledger is a directory of 300+ AI tools for accountants and bookkeepers, with editor scores that are never for sale, a verdict and a last verified date on every entry. For financial statement review, start with the audit and fraud detection category, use the finder to match tools to your practice, or put two tools side by side with compare. Check each shortlisted tool for accuracy evidence, audit trail features, UK GDPR terms and integration with your existing systems, then run the validation test above.
- * *
Sources
The sources below are the primary benchmarks and practitioner references cited in this article.
- FinVerBench: Benchmark Validity and Calibration in Large Language Model Financial Statement Verification
- Accelerate your financial statement analysis with Amazon Bedrock and generative AI
Recommended
- Why AI reduces accounting errors: a 2026 guide)
- AI in accounting explained: the 2026 professional guide
- AI tools for the financial close process: 2026 guide)